Pipeline SDK Design
Overview This SDK delivers a streamlined, modern interfaces, engineered to facilitate the rapid development, execution, and management of sophisticated multimedia pipelines. By implementing a high-level abstraction layer, the SDK encapsulates complex underlying GStreamer based mechanisms — including element negotiation, signal management, event loops, and state transitions — allowing engineers to prioritize core application logic over boilerplate framework intricacies. Key Capabilities The wrapper empowers developers to architect advanced multimedia and AI-enhanced workflows with precision and efficiency. It supports the seamless integration of diverse components, such as video capture sources, signal processing nodes, machine learning inference engines, graphical overlays, and rendering outputs. Uniquely designed to decouple implementation from the underlying framework, the SDK eliminates the need for deep GStreamer expertise or compile-time dependencies on GStreamer headers, ensuring a clean, robust, and accessible development experience.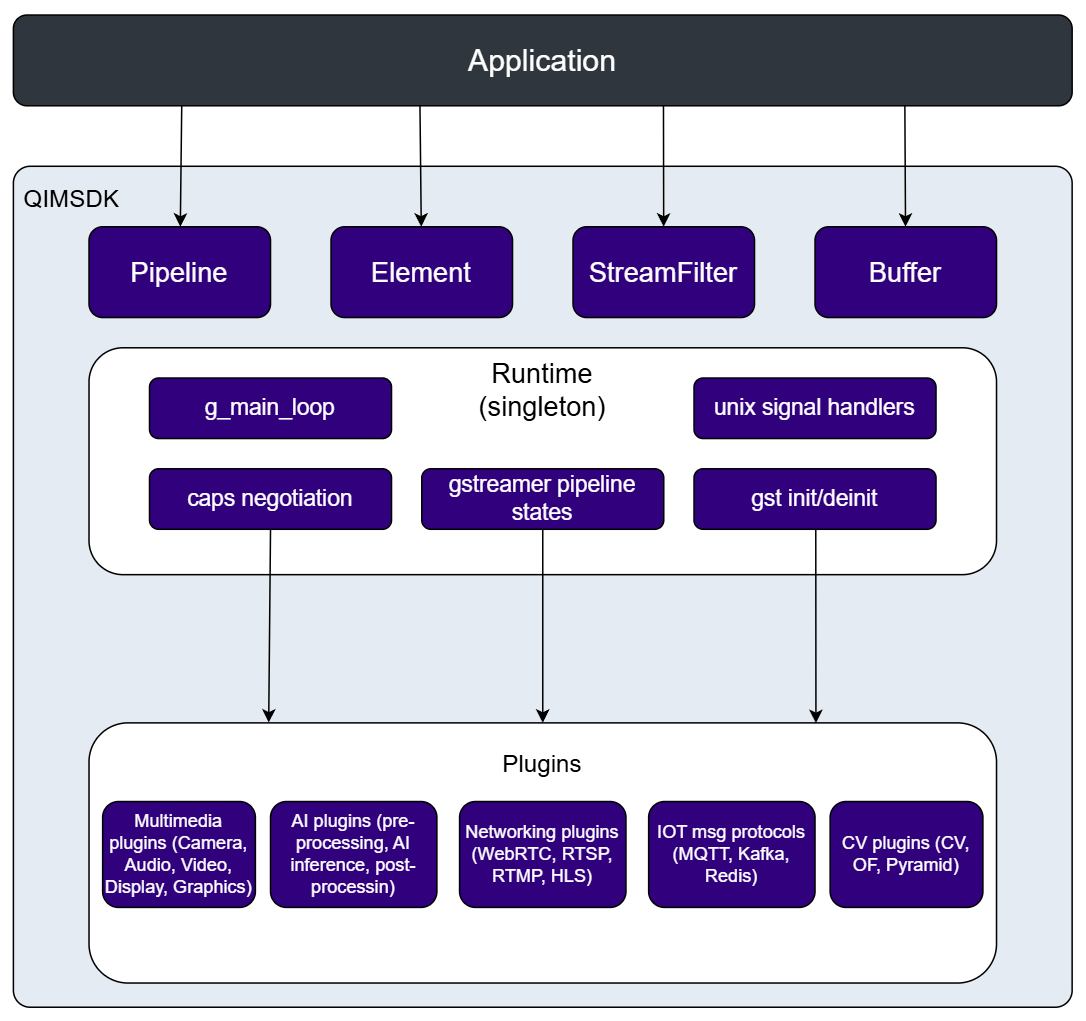
APIs
Public APIs:Pipeline— build & control pipelines fluently.Element— generic element wrapper with variadic property setting, and state control. It can be instantiated at create time as well as at runtime to update the pipeline. Some elements have special functions which can be controlled by dedicated element types. Those derived types can be used as a plainElementif the special functions are not needed.AppSrc— app-facing source for zero-copy buffer pull. Feeds application-produced buffers into the pipeline through a callback or a direct push API, and can signal EOS.AppSink— app-facing sink for zero-copy buffer push. Delivers pipeline output back to application code with zero copy.CamSrc— built-in camera element that exposes an API for capturing images at runtime.MLVConverter— ML video converter (qtimlvconverter). Exposes an API for custom pre-processing implementation in application code through a callback.MLPostprocess— ML postprocess element (qtimlpostprocess). Exposes an API for custom post-processing implementation in application code through a callback. The callback’s output type annotation selects the ML task (classification, object detection, pose estimation, depth estimation, segmentation, raw tensors).MLVideoONNXBin— ONNX inference bin (qtimlvideoonnxbin). Exposes an API for custom pre-processing and post-processing implementation through callbacks.MLVideoQNNBin— QNN inference bin (qtimlvideoqnnbin). Exposes an API for custom pre-processing and post-processing implementation through callbacks.MLVideoSNPEBin— SNPE inference bin (qtimlvideosnpebin). Exposes an API for custom pre-processing and post-processing implementation through callbacks.MLVideoTFLiteBin— TFLite inference bin (qtimlvideotflitebin). Exposes an API for custom pre-processing and post-processing implementation through callbacks.
Buffer— opaque buffer that bridges native GStreamer memory with timestamp helpers and zero-copy paths.StreamFilterand derived concrete stream helpers:VideoFilter(all RAW formats - YUV, RGB, bayer),H264Filter,TensorFilter,TextFilter,AudioFilter,ImageFilter. These filters are used to set characteristics of the streams.- Logging controls —
SetImsdkLogLevel()andSetImsdkGstLogMode()select the SDK’s log verbosity and whether GStreamer’s output is simplified or passed through raw. See Logging and Diagnostics.
Pipeline
Purpose A convenient wrapper around aGst.Pipeline that:
- Builds pipelines using element factory names or pre-constructed wrapper elements.
- Manages pipeline lifecycle and execution state.
- Performs delayed linking for dynamic/request-pad elements automatically via
pad-added.
- Create and own the underlying
Gst.Pipelineinstance. - Add elements, assign properties, and insert caps filters.
- Link elements (immediately when possible, deferred otherwise).
- Manage the full pipeline lifecycle (
prepare,start,wait,stop). - Install bus watches to handle
ERROR,EOS, and state transitions. - Integrate with runtime shutdown notifications.
execute() starts the pipeline, blocks until EOS/error/termination, and tears it down.
qtdemux is an example of the delayed linking described above: its src pads appear only once the container has been parsed, so the demux → parse link is completed automatically when the pad shows up. No pad-added handling is needed in application code.add()’s optional key/value pairs are the element’s properties, validated as soon as the element is added — an unknown property raises ValueError naming the property and the element type, instead of being silently ignored:
A link between two elements that both have only static pads and no common caps fails immediately with
RuntimeError naming both elements. A deferred link that never resolves surfaces at run time instead; on error the pipeline logs which pads stayed unlinked.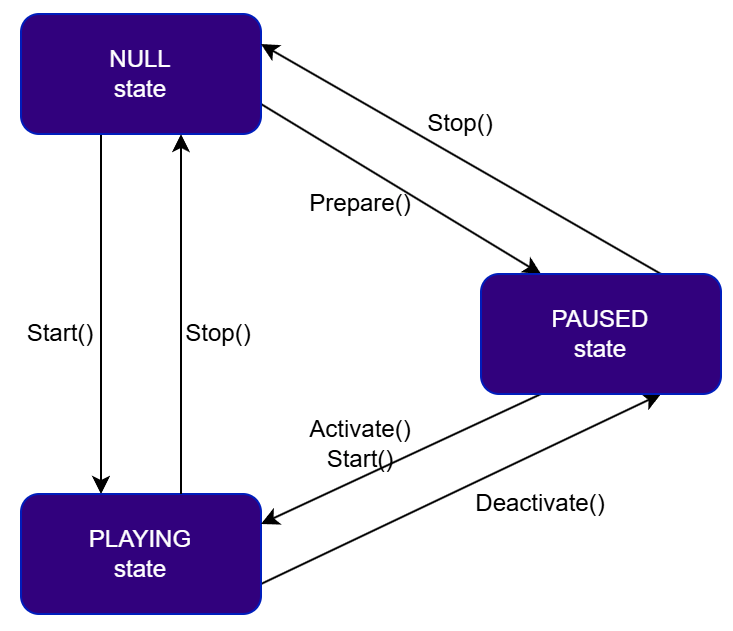
execute() performs the whole NULL → PLAYING → NULL cycle, so most applications never call the individual transitions. prepare(), activate(), and deactivate() — the transitions through PAUSED — are covered in Advanced state control.
To run the pipeline while the application does other work, split
execute() apart:
stop() tears the pipeline down as fast as it can. Every element goes to NULL immediately and whatever buffers are still in flight — queued between elements, held inside an encoder, not yet written by a sink — are discarded. This is usually what you want: the pipeline stops without delay.
Some pipelines must not lose those buffers, and for them eos(True) changes the shutdown sequence. Instead of stopping straight away, stop() sends an end-of-stream event into the pipeline. The event travels downstream element by element; each element finishes processing the data it has already accepted, passes the event on, and the sinks report it back on the bus. Only once that end-of-stream notification comes back does stop() tear the pipeline down. Nothing that had already entered the pipeline is dropped.
The trade-off is shutdown latency: stop() now blocks until the last buffer has made it through the whole graph, which takes as long as the remaining data needs.
Use eos(True) when the tail of the stream is part of the result:
- Muxed recordings. Containers such as MP4 and MKV are written by a muxer (
mp4mux,matroskamux) that writes its index and header metadata — themoovatom, in MP4’s case — only on end-of-stream. Cut it off early and the file is left incomplete, often unplayable rather than merely short. - Encoders with buffered frames. Encoders keep several frames in flight for B-frames, lookahead, and similar optimizations. End-of-stream is what makes the encoder flush those frames downstream; without it the tail of the recording is simply missing.
- Any sink where losing the final buffered data is unacceptable — file sinks, muxed outputs, and applications that expect to receive every frame through
AppSink.
eos() off (the default) when the newest data is all that matters and stopping promptly is preferable — live preview to a display, a camera feed on screen, or writing self-contained files where each buffer is already complete on its own (JPEG frames through multifilesink, for example, which needs no finalization).
If the pipeline has already reached end-of-stream on its own — a file source that ran out of data, for instance —
stop() detects it and tears down immediately instead of sending a second event and waiting again. Enabling eos(True) therefore costs nothing for pipelines that end naturally; it only matters when you stop a pipeline that is still running.NULL.
Accessing elements at run time
Unlike the C++ SDK’s
get<T>(), Python has no compile-time generics, so the type is passed as an ordinary argument. To reach a specialized element’s own API (for example CamSrc.image_capture()), pass the class as as_type:
get() reaches any element by name while the pipeline is loaded or playing:
get() returns a new Element wrapper on every call, each referencing the same underlying Gst.Element. There is no cached identity to keep in sync — call it again whenever you need the element.- Deploying one script across variants — the same application against a built-in camera, a USB camera, or an RTSP stream, switching source and format per device.
- Tuning without code changes — resolution, framerate, model path, or delegate changed on the target, without touching the script.
- Keeping topology under review — the pipeline shape lives in a file that can be diffed and versioned on its own.
get() reaches them as usual.
pipeline:, which takes three independent child keys:
Within
elements:, each entry needs type (the factory name) and name (the instance name); every remaining key is applied as a property of that element. An entry with type: filter inserts a stream filter instead, described by a video:, image:, h264:, tensor:, text:, audio:, or raw caps: block.
links: mirrors link() — one sequence per chain, so the branching pipeline shown earlier becomes:
from_yaml() takes the configuration content itself, so read the file first:
qtimlpostprocess element named postprocessing, the application can attach its post-processing callback without the topology being hard-coded:
Element
Purpose Generic wrapper around aGst.Element with fluent, variadic property setting. Can be instantiated at create time or used at runtime to update a live pipeline. Serves as the base class for all specialized element types.
Key Responsibilities
- Create GStreamer elements from a factory name.
- Provide fluent, variadic property setting for all common types and
StreamFilter(caps). - Implement pad linking/unlinking with error checking.
- Support state publication to pipeline (
sync,deactivate,stop). - Expose per-pad configuration through
Port. - Serve as the base class for specialized wrappers.
Per-pad configuration with Port
Some elements are configured per pad rather than per element — a compositor’s inputs each have their own position, size, and alpha.
input() and output() return a Port for one pad, which carries the same fluent, validated set():
AppSrc
PurposeAppSrc wraps the appsrc element, the entry point for feeding application-produced buffers into a pipeline. It manages the need-data/enough-data signal plumbing so the application only has to supply buffers, either from a callback or by pushing them directly.
Key Responsibilities
- Validate that the wrapped element is indeed an
appsrc. - Register and dispatch the underlying
need-dataandenough-datasignals. - Let the application supply buffers on demand through
set_buffer_producer(), or push them directly withpush_buffer(). - Signal end-of-stream on this element’s output.
- Manage lifetime of the connected signal handlers.
AppSrc.Format mirrors appsrc’s own format property — an IntEnum with DEFAULT, BYTES, TIME, BUFFERS, PERCENT.
AppSink
PurposeAppSink wraps the appsink element, the exit point that delivers pipeline output back to application code. It pulls samples through appsink’s action signals and hands them to the application as Buffer.
Key Responsibilities
- Validate that the wrapped element is indeed an
appsink. - Pull samples via appsink’s action signals and convert them into
Buffer. - Deliver each buffer to the application through
set_buffer_consumer(). - Deliver the first (preroll) sample separately through
set_preroll_handler(). - Notify the application of end-of-stream through
set_eos_handler(). - Manage lifetime of the connected signal handlers.
CamSrc
PurposeCamSrc wraps the qtiqmmfsrc camera source element and exposes its still/burst image-capture action signals as ordinary method calls, so an application can trigger a snapshot without touching GStreamer signals directly.
Key Responsibilities
- Validate that the wrapped element is indeed a
qtiqmmfsrc. - Trigger still or burst image capture through
image_capture(). - Cancel any pending capture request through
cancel_capture().
Reach a
qtiqmmfsrc already in the pipeline through Pipeline.get()’s as_type argument to use its capture API:
MLVConverter
PurposeMLVConverter wraps the qtimlvconverter element, which converts raw video frames into the input tensor format expected by a model. Beyond the properties available on the generic Element, it lets the application replace the built-in conversion with its own implementation through a callback.
Key Responsibilities
- Validate that the wrapped element is a
qtimlvconverter. - Convert incoming video frames into model input tensors.
- Optionally delegate the conversion to an application-supplied pre-process callback.
MLPostprocess
PurposeMLPostprocess wraps the qtimlpostprocess element, which decodes model output tensors into ML metadata attached to the frame. It lets the application replace the built-in decoding module with its own implementation through a callback.
Key Responsibilities
- Validate that the wrapped element is a
qtimlpostprocess. - Decode output tensors into ML metadata (classifications, detections, poses, depth maps, segmentations, or raw tensors).
- Optionally delegate the decoding to an application-supplied post-process callback.
- Select the callback’s ML task automatically from its output-parameter type annotation.
set_handler() takes a single callback and, unlike a per-task setter, infers which ML task it handles from the type annotation on the callback’s output parameter. The callback takes either 3 parameters (mlframe, mlparams, results) or 4 (mlpostprocess, mlframe, mlparams, results); the output parameter must be annotated with one of the marker types below.
ML inference bins
Purpose The ML video bins wrap a full pre-process → inference → post-process chain into a single element, so a whole AI branch can be added to the pipeline as one node instead of being assembled from separate elements. Four bins are available, one per inference runtime:
All four expose an identical API and differ only in the wrapped element and the runtime-specific properties. Each accepts a custom pre-process callback, a custom post-process callback, or both.
Key Responsibilities
- Validate that the wrapped element matches the expected bin factory.
- Run pre-processing, inference, and post-processing inside a single element.
- Optionally delegate pre-processing to an application-supplied callback via
set_preprocess_handler(). - Optionally delegate post-processing to an application-supplied callback via
set_postprocess_handler().
preprocess-*, inference-*, and postprocess-*. For example inference-model on the bin corresponds to model on a standalone inference element, and postprocess-labels corresponds to labels on a standalone qtimlpostprocess.
Set
preprocess-engine to none to disable the internal pre-processing path when you supply your own pre-process callback.The bin’s callbacks are
set_preprocess_handler() and set_postprocess_handler() — distinct names from the standalone MLVConverter.set_handler() and MLPostprocess.set_handler(), since a bin exposes both stages on one object.MLVideoONNXBin, MLVideoQNNBin, MLVideoSNPEBin, and MLVideoTFLiteBin; substitute the concrete class name for <Bin>.
Buffer
Purpose Unified buffer abstraction over native GStreamer memory. Provides read/write access, timestamp metadata (pts, dts, duration), resize support, and zero-copy transfer between AppSink and AppSrc. Key Responsibilities- Own and manage mapping/unmapping of underlying
Gst.BufferorGst.Sample. - Provide read/write access to buffer memory.
- Support resizing and writable allocation for AppSrc.
- Carry timestamps (PTS/DTS/duration) and apply them back to
Gst.Buffer. - Enable zero-copy extraction using
take_gst_buffer().
StreamFilter
Purpose StreamFilter describes the characteristics of a media stream between two pipeline stages so they can negotiate concrete parameters rather than relying on defaults. Without explicit parameters, adjacent components may fall back to suboptimal formats, trigger implicit conversions, or produce mismatched configurations. Specialized subtypes provide fluent, type-safe setters for each domain. Raw caps strings are also accepted for cases not covered by typed setters or when copying directly from gst-launch output. When to Use StreamFilter- When two adjacent stages can interoperate in multiple ways, and you want to select explicit parameters instead of relying on defaults.
- When you need to optimize latency or performance by avoiding implicit conversions (e.g., choose a hardware-friendly pixel format).
- When you want predictable behavior across platforms (e.g., lock color range/primaries/transfer/matrix).
- When you integrate tensors for AI/ML and must precisely specify dimensions and element types.
- When you need a human-readable summary of the stream parameters for logs and debugging.
StreamFilter is not an Element and is never added to a pipeline with add(). It is always attached between stages with Pipeline.add_stream_filter(name, filter), which internally creates a capsfilter element and applies the filter’s caps to it. The base StreamFilter class itself only exposes a raw-caps-string constructor and to_string(); the fluent per-domain setters (.format(), .resolution(), .framerate(), …) live on the typed subclasses such as VideoFilter.
Usage
Typed subclass
VideoFilter
Purpose Configures a raw video stream (YUV, RGB, Bayer) between a camera source and any downstream processing or display element. Supports format, resolution, framerate, colorimetry, interlace mode, and pixel aspect ratio. Key Responsibilities- Produce caps with standard raw video attributes: format, resolution, framerate, colorimetry, interlace mode, pixel aspect ratio, etc.
Usage
We can achieve the same results in two different ways:
Typed (enum) API - if you want IDE autocompletion and guardrails against typos. Ideal for most application code.
H264Filter
Purpose Configures an encoded H.264 stream between an encoder and a downstream parser or muxer. Supports resolution, framerate, stream-format, alignment, profile, and level. Key Responsibilities- Specify resolution, framerate, stream-format, alignment, profile, level.
- Insert
codec_databuffers. - Attach arbitrary name/value string properties.
Usage
TensorFilter
Purpose Configures an ML tensor stream with explicit data type and shape (e.g., UINT8, NHWC). Not needed in a full inference pipeline — when preprocess, inference, and postprocess elements are all present, tensor parameters are negotiated automatically. Use TensorFilter when:- The preprocessing stage does not have model dimension information
- You need exact tensor data output from the inference plugin
- Declare element type (e.g.,
UINT8,FLOAT32) for tensors. - Specify shape (dimensions). Supports:
- Single tensor: a flat list of ints (e.g.,
1, 520, 520, 3). - Multiple tensors: a list of lists (e.g.,
[[1,3,H,W], [1,32]]) when needed.
- Single tensor: a flat list of ints (e.g.,
Usage
We can achieve the same results in two different ways:
Typed (enum) API - if you want IDE autocompletion and guardrails against typos. Ideal for most application code.
TextFilter
Purpose Configures a raw text stream (text/x-raw) for pipelines that carry textual data such as metadata, subtitles, or logs. Minimal by design — attach only the fields you need using.add("key=value").
Key Responsibilities
- Provide a lightweight caps descriptor for text (
text/x-raw) without enforcing a schema. - Let callers attach arbitrary properties (e.g., encoding/charset, language, packetization hints) using
.add("key=value").
Usage
ImageFilter
Overview Used exclusively with CamSrc (qtiqmmfsrc) to enable and link its dedicated image capture pad. Without ImageFilter, the image pad is not requested, not activated, and produces no buffers. It is a structural enabler, not a processing stage — it is not intended for general image processing or frame extraction from video sources.
ImageFilter is used to:
- Enable the image output pad exposed by
CamSrc(qtiqmmfsrc) - Attach that pad to the pipeline so the source can activate image capture
- Provide a concrete sink target required by GStreamer for pad activation
- Generic image processing
- Frame extraction from arbitrary video sources
- Replacement of
VideoFilterorAppSink
CamSrc(qtiqmmfsrc) exposes a dedicated image pad that remains inactive unless linked.ImageFilterexplicitly exists to satisfy this requirement.- Without
ImageFilter, the image pad:- Will not be requested
- Will not be activated
- Will not produce buffers
ImageFilter a structural enabler, not a processing stage.
Usage
AudioFilter
Purpose Configures a raw PCM audio stream with sample format, channel count, sample rate, and layout. Use this to ensure audio converters and sinks negotiate exactly the format your hardware supports rather than inserting an implicit resampler. Key Responsibilities- Set audio sample format (e.g.,
S16LE,F32LE) to match HW/SW capabilities. - Define channels and rate for correct resampling/mixing.
- Choose layout (
interleavedvsnon-interleaved) to align with downstream expectations.
Usage
We can achieve the same results in two different ways:
Typed (enum) API - if you want IDE autocompletion and guardrails against typos. Ideal for most application code.
Logging
The SDK can either simplify GStreamer’s log stream into a compact, uniform format or step aside and let GStreamer log raw, withGST_DEBUG fully in control. Both modes, the verbosity levels, the integration with Python’s logging module, and the ordering constraint on configuring them are covered in Logging and Diagnostics.
QIM SDK Nodes
All nodes are executed by GStreamer elements under the hood. Most elements are handled through theElement base class. However, elements that provide additional functionality — such as application buffer interfaces in appsink and appsrc, or image-capture signals in camera sources like qtiqmmfsrc — have a specialized Python wrapper class.
If you do not need these extra capabilities (for example, image capture), you can still use these elements via the generic Element base class without any limitations for standard data processing.
Below is a table listing all supported elements and the corresponding QIM SDK Python wrapper classes used to work with them.
Sources
AI
Multimedia
Common Application Design
Create pipeline with config file
The SDK supports fully declarative pipeline construction using YAML. A YAML pipeline describes elements and links between them, which are translated at runtime into a GStreamer pipeline. TopLevel Structure A YAML pipeline file has a single top-level key:elements is an ordered list of pipeline elements. Each element entry defines:
- The GStreamer element type
- A unique name used for linking
- Optional properties
- Optional filter configuration
type: GStreamer element factory name, orfiltername: Unique identifier within the pipeline- properties: Any remaining key/value pairs are passed directly to the element as GStreamer properties
type: filter and are further specialized by their configuration block.
Stream Filter
links defines explicit connection paths between elements.
Each entry is an ordered list of element names. Elements are linked sequentially from left to right.
Multi-Model Daisy Chain
Below is shown a logical diagram of an AI daisy chain pipeline with sequential and parallel inferencing. The same could be handled by a straight sequential pipeline of inference bins. But we must set manually the source for every inference bin.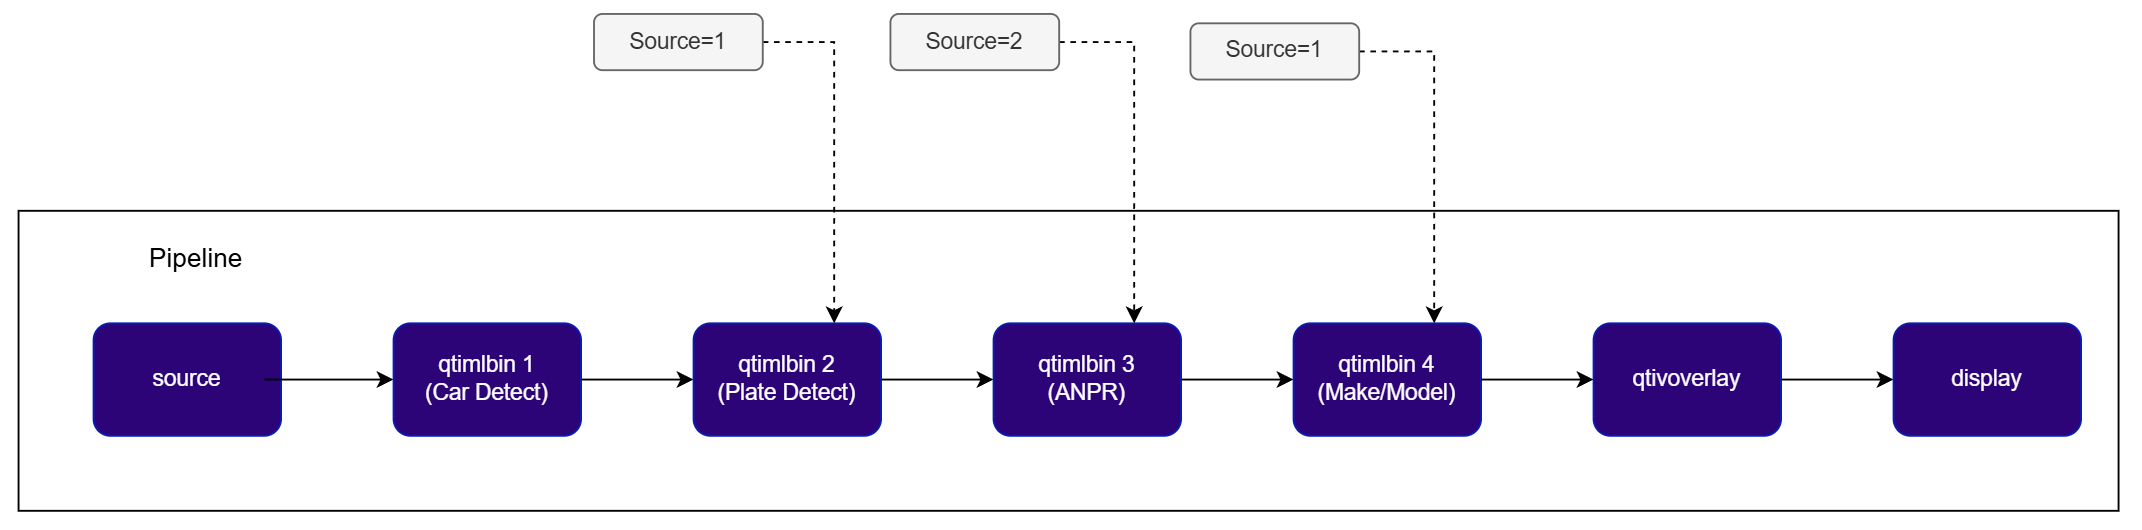
Try me
Try me
Several
.add(...) calls in this example had missing/mismatched quotes in the source PDF (e.g. a stray closing paren instead of a closing quote, or a missing leading quote). These have been corrected below where unambiguous. One inline comment truncated at the page margin was completed using the identical sentence found in the prose above.Custom Postprocessing for YOLOv8 (Detection)
QIM SDK implements AI model post-processing through dedicated modules that take tensors as input and produce predictions. All remaining complexity — such as batching, daisy-chaining, image mask support — is encapsulated within the post-processing plugin. This makes the post-processing module API an ideal integration point for application-specific post-processing logic. As a result, applications do not need to handle batching, chaining, image masks, or ML metadata themselves. We will implement a specialized post-processing module to manage bindings with the application.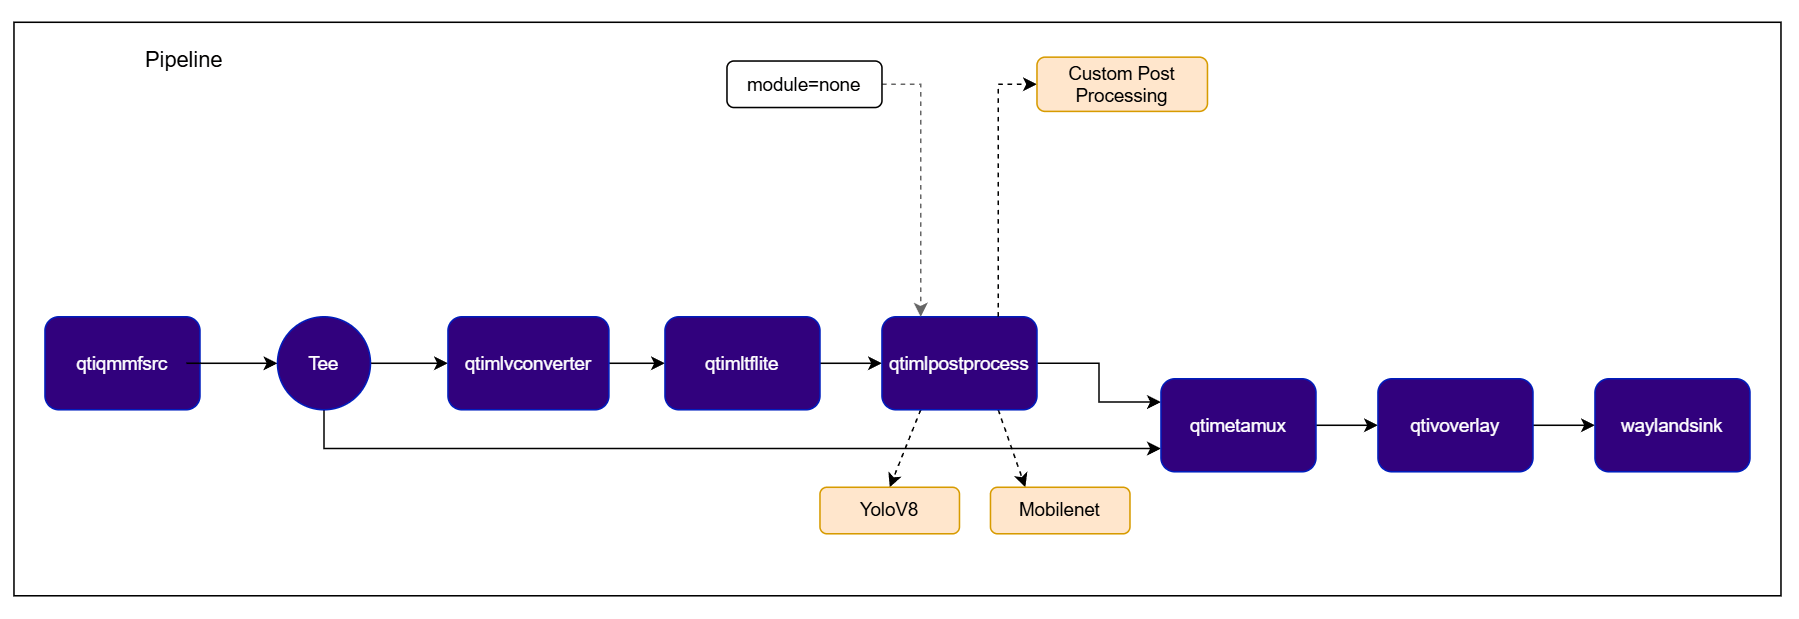
qtimlpostprocess element via MLPostprocess.set_handler(...).
Typical pipeline segment:
- Preprocess frame/tensors (
qtimlvconverter) - Run ML inference (
qtimltflite) - Convert raw tensors in custom callback (
qtimlpostprocess)
ImageClassificationsObjectDetectionsPosesDepthMapsSegmentationsTensors
mlframe (read-only model tensors)
Passed to every callback. Its tensors list holds one entry per model output tensor, each exposing:
type: tensor element typedimensions: tensor shapedata: raw tensor memory (as amemoryview)size: tensor bytes
mlparams (runtime metadata and context)
mlparams carries key/value fields provided by the pipeline and preprocessing/postprocess context. Commonly used keys:
input-tensor-widthinput-tensor-heightinput-tensor-region(an(x, y, width, height)region)
- Callbacks annotated with
ImageClassifications,AudioClassifications,ObjectDetections,Poses,DepthMaps, orSegmentationsfill the corresponding output metadata container. - A callback annotated with
Tensorsfills an outputTensorsobject for downstream tensor stages. mlframeis read-only and must not be modified.
out. Field meanings:
name: class label textconfidence: prediction confidencecolor: optional UI/overlay colorextra: optional metadata map
out. Field meanings:
left,top,right,bottom: normalized box coordinatesname,confidence,color: class infolandmarks: optional keypointsextra: optional metadata map
mlframe: read-only model output tensors.mlparams: runtime metadata (for example:input-tensor-width,input-tensor-height,input-tensor-region).segmentations: output container to fill.
labels: per-pixel semantic labels.colors: per-pixel colors; index-aligned withlabels.n_rows,n_columns: segmentation map dimensions.extra: optional metadata fields.
out. Field meanings:
keypoints: list of keypoints (name,x,y,confidence,color)links: list of keypoint links describing skeleton connectionsname,confidence,extra: pose-level metadata
out. Field meanings:
values: per-pixel depth valuescolors: per-pixel pseudo-color valuesn_rows,n_columns: depth map shapeextra: optional metadata map
out is owned and writable; callback typically:
- validates input tensors from
mlframe - copies/selects required tensors into
out - updates output tensor dimensions/order if needed
mlframe: input tensors from inference (read-only)mlparams: runtime metadata (input sizes, region, etc.)output: semantic objects to be filled by callback- return
Trueon valid output - return
Falseon validation/decode failure
mlframe: input tensors from inference (read-only)mlparams: runtime metadata/contextoutput: writable output tensors for downstream tensor stage- return
Trueon valid output - return
Falseon validation/decode failure
Try me
Try me
Check application source code on GitHub:
qimsdk_ref_external_postprocess_detection_yolov8.pyPre-built application on device: /usr/bin/qimsdk_ref_external_postprocess_detection_yolov8.pyDownload Required Files
If the downloaded model file is a
.zip archive, extract it on your host machine before copying: unzip filename.zipSome AI Hub models require running the AI Hub export/optimize step for your target runtime before the downloaded file is usable — download alone isn’t always sufficient.1
Copy Files to Device
Also copy an MP4 (H.264) file for the pipeline’s video input, or update the pipeline’s
location property to point to your own file.2
Run the application